
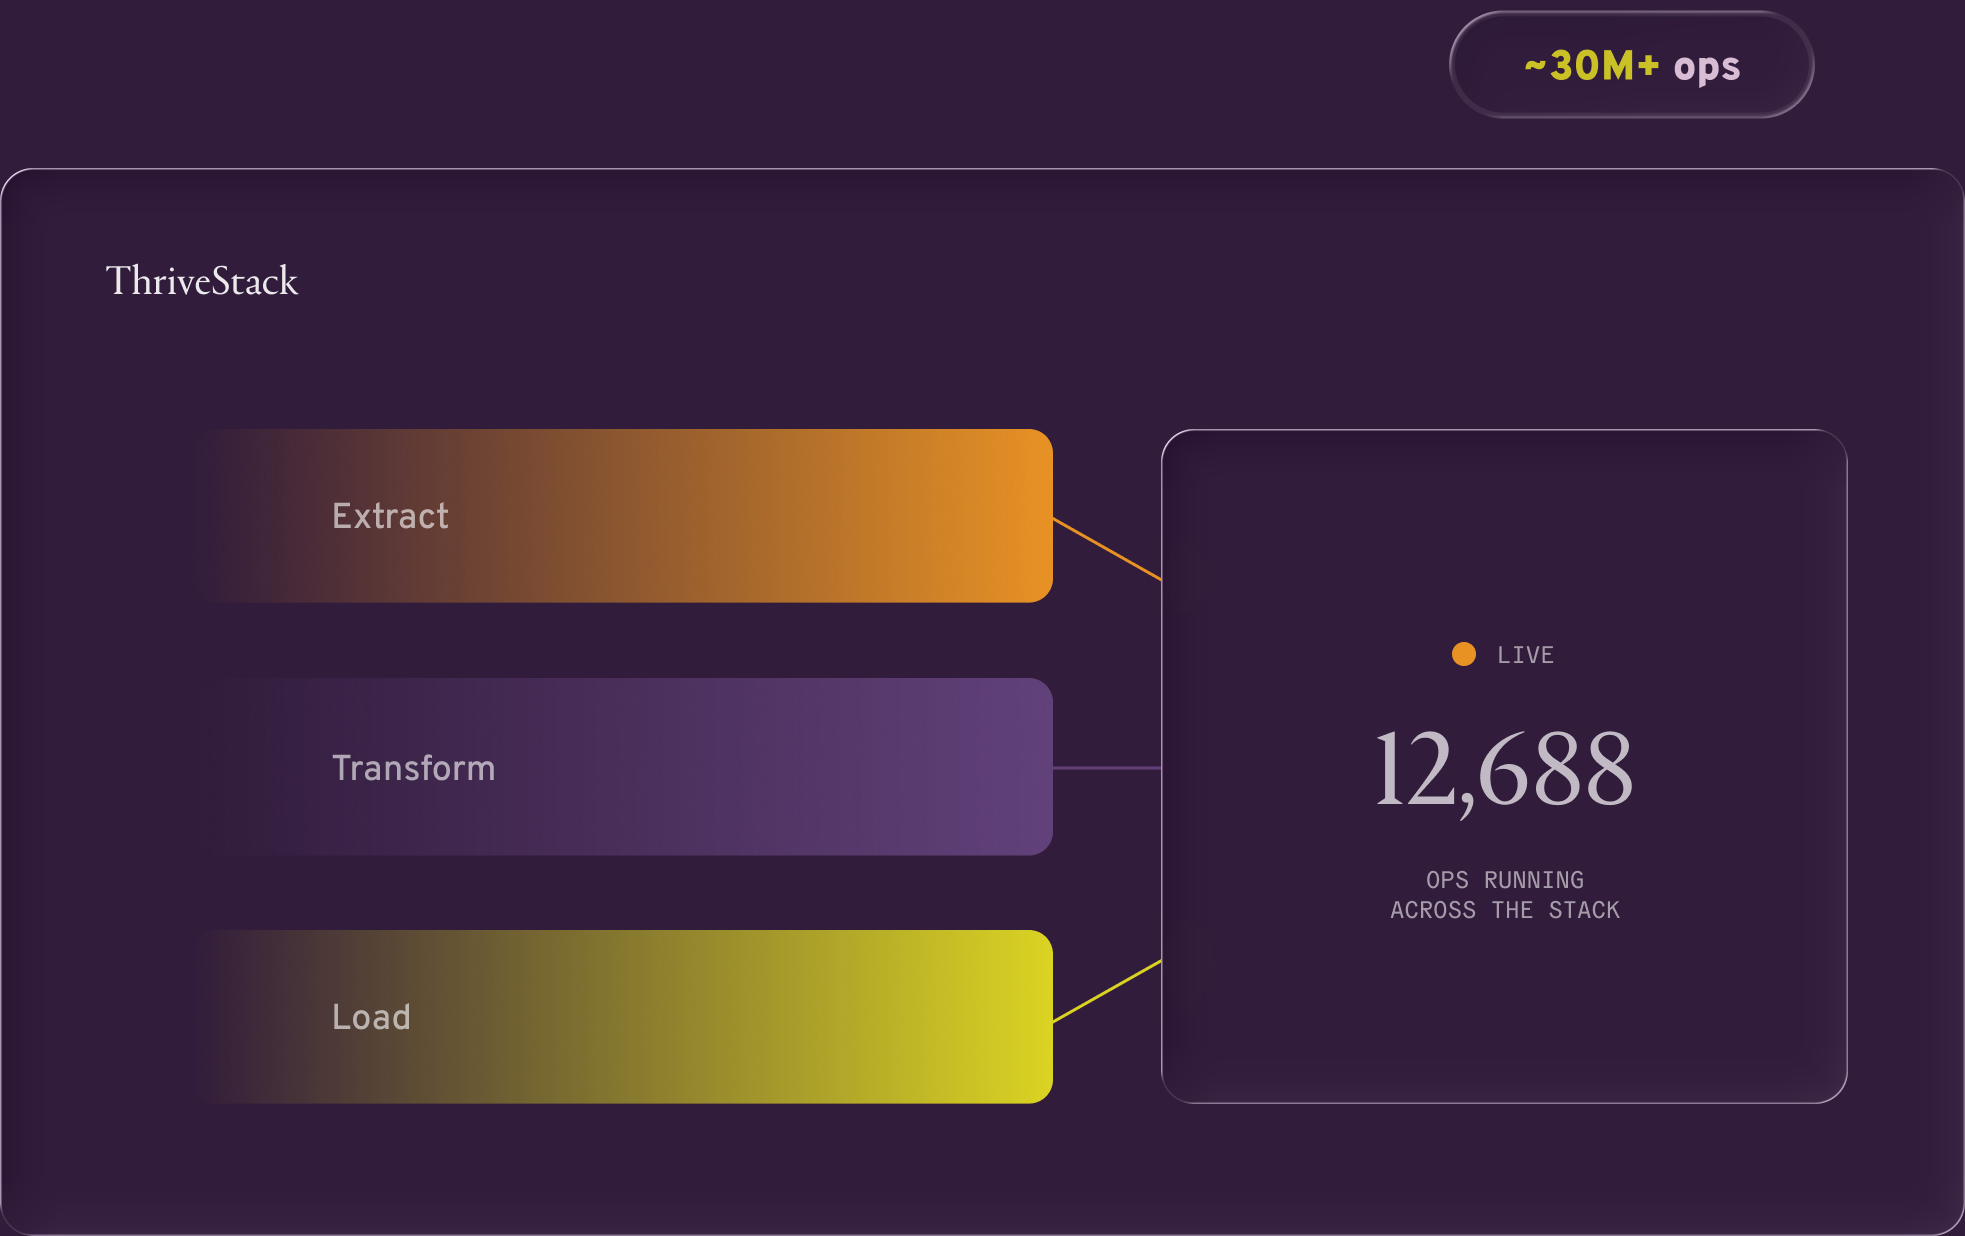


ThriveStack is Thrive's proprietary ETL platform — built in-house since 2018. It extracts data from every major ad platform, CRM, and analytics tool, transforms it into a consistent format, and loads it into a centralized data warehouse (BigQuery or Snowflake). The result is accurate, automated marketing data that's fresh every day and accessible to any reporting tool.


Each client's data is kept completely separate — never shared across accounts or used beyond that client's program. Access management is built into the infrastructure: role-based controls determine which internal teams can access which client data, and everything is managed systematically rather than improvised. For specific security certifications and compliance details, contact the Thrive team directly.
Looker Data Studio is the default — it connects directly to BigQuery and produces clean, automated dashboards without additional licensing. If a client has existing infrastructure in Tableau, Power BI, or another tool, ThriveStack connects to those directly. Thrive doesn't lock clients into a proprietary reporting environment.
Yes. ThriveStack ingests CRM data from Salesforce, HubSpot, and other major CRM platforms — blending pipeline and revenue data with ad platform performance data to enable closed-loop reporting. This is what makes it possible to optimize campaigns against qualified pipeline and closed revenue rather than just digital conversion proxies.
ETL stands for Extract, Transform, Load — the process of pulling data from multiple sources, cleaning and standardizing it, and loading it into a centralized database. A marketing agency managing campaigns across Google, Meta, TikTok, LinkedIn, CRM systems, and analytics tools needs ETL infrastructure to make all that data consistent, accurate, and usable for decisions. Without it, reconciliation happens manually and data reliability degrades.


